
EpiFlow (Epigraph-Guided Flow Matching) is a method for safe offline reinforcement learning. It formulates the problem as state-constrained optimal control: safety is a hard state constraint that must hold at every timestep, and performance is captured by a reward. The resulting value function satisfies a Hamilton–Jacobi–Bellman equation, which EpiFlow approximates from fixed data by learning an epigraph feasibility value function and extracting policies via flow matching. Across Boat Navigation, Safety-Gymnasium and Bullet-Safety-Gym, it achieves competitive returns with near-zero constraint violations.
Safe offline RL asks for a reward-maximizing policy from a fixed dataset $\mathcal{D} = \{(x_t, a_t, r_t, \ell_t, x_{t+1})\}$, with no further interaction with the environment. With a safety function $\ell(x)$ and failure set $\mathcal{F} = \{x : \ell(x) < 0\}$, the goal is the state-constrained value function
$$ V(x) = \sup_{\pi}\ \Big[\sum_{k=0}^{\infty} \gamma^k r(x_k)\ \Big|\ x_0 = x\Big] \qquad \text{s.t.}\quad x_t \notin \mathcal{F},\ \ \forall t \ge 0 . $$Only policies whose trajectories stay outside $\mathcal{F}$ at every timestep are feasible, and two standard families of methods struggle with this for opposite reasons.
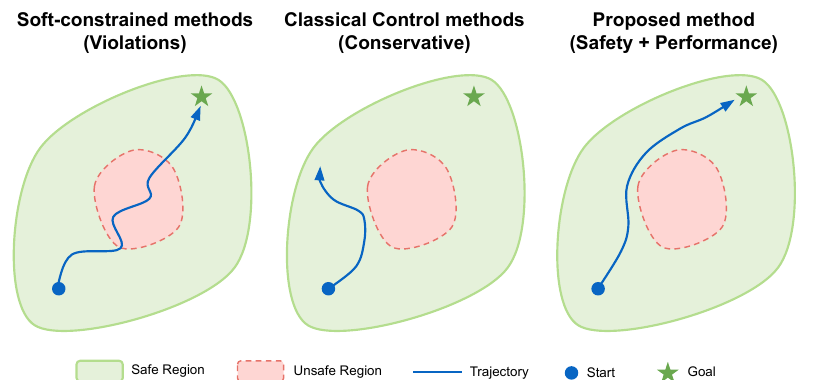
Soft-constraint methods lose the guarantee. Lagrangian and cost-budget approaches (BCQ-Lag, BEAR-Lag, CPQ, COptiDICE, C2IQL) bound expected cumulative cost. That permits non-zero violation risk, is sensitive to distributional shift, and becomes unstable or overly conservative when unsafe transitions are rare in the data.
Classical safety methods lose performance. Hamilton–Jacobi reachability and control barrier function approaches (FISOR, NCBF, V-OCBF) provide stronger safety, but typically act as safety filters that combine separately learned safety and performance values through a switching rule, which often sacrifices return. Solving the underlying HJB equation directly is intractable in high dimensions, and runtime shielding or planning methods need online interaction, a dynamics model, or a verified backup controller — none of which is available offline.
EpiFlow introduces a scalar return threshold $z$ and an auxiliary epigraph feasibility value
$$ \hat V(x_t, z_t) = \sup_\pi \min\Big\{ \sum_{k=t}^{\infty} \gamma^{k-t} r(x_k) - z_t,\ \ \min_{s \ge t} \gamma^{s-t} \ell(x_s) \Big\}, \qquad V(x) = \sup\{ z \in \mathbb{R} \mid \hat V(x, z) \ge 0 \}. $$$\hat V(x,z) \ge 0$ exactly when some policy both achieves return at least $z$ and never enters $\mathcal{F}$, so the original constrained value is the largest feasible threshold. The threshold evolves as $z_{t+1} = (z_t - r(x_t))/\gamma$, which keeps the augmented state $(x, z)$ Markov and lets $\hat V$ be learned from offline transitions with value-based methods.
Theorem (Bounded Epigraph Value Recursion). For a deterministic state-constrained MDP with bounded reward and $\gamma \in (0,1)$, let $V_r$ be the optimal reward value and $V_s$ the optimal safety value. Then the epigraph value satisfies
$$ \text{(i)}\ \ \hat V(x_t, z_t) = \min\big\{ \ell(x_t),\ \gamma\, \hat V(x_{t+1}, z_{t+1}) \big\}, \qquad \text{(ii)}\ \ \hat V(x_t, z_t) \le \min\big\{ V_r(x_t) - z_t,\ V_s(x_t) \big\}. $$Part (i) alone is ill-conditioned offline: it is structurally identical to a pure safety-value recursion, and $z$ enters only through a shifted argument. With limited data, a network can minimize training error by ignoring $z$ and collapsing $\hat V(x,z)$ to $V_s(x)$. Part (ii) injects an explicit linear dependence on $z$ through $V_r(x) - z$. EpiFlow enforces it with a one-sided regularizer,
$$ \mathcal{L}(\theta) = \mathcal{L}_{\hat V}(\theta) + \lambda\, \mathbb{E}\Big[\max\big(0,\ \hat V_\theta(x,z) - \min\{V_r(x) - z,\ V_s(x)\}\big)\Big], $$so the recursion pins the fixed point from below while the bound prevents collapse from above. To avoid overestimating out-of-distribution actions — a safety risk here — $\hat Q(x,z,a)$ is fit on dataset transitions and distilled into $\hat V_\theta$ by expectile regression.
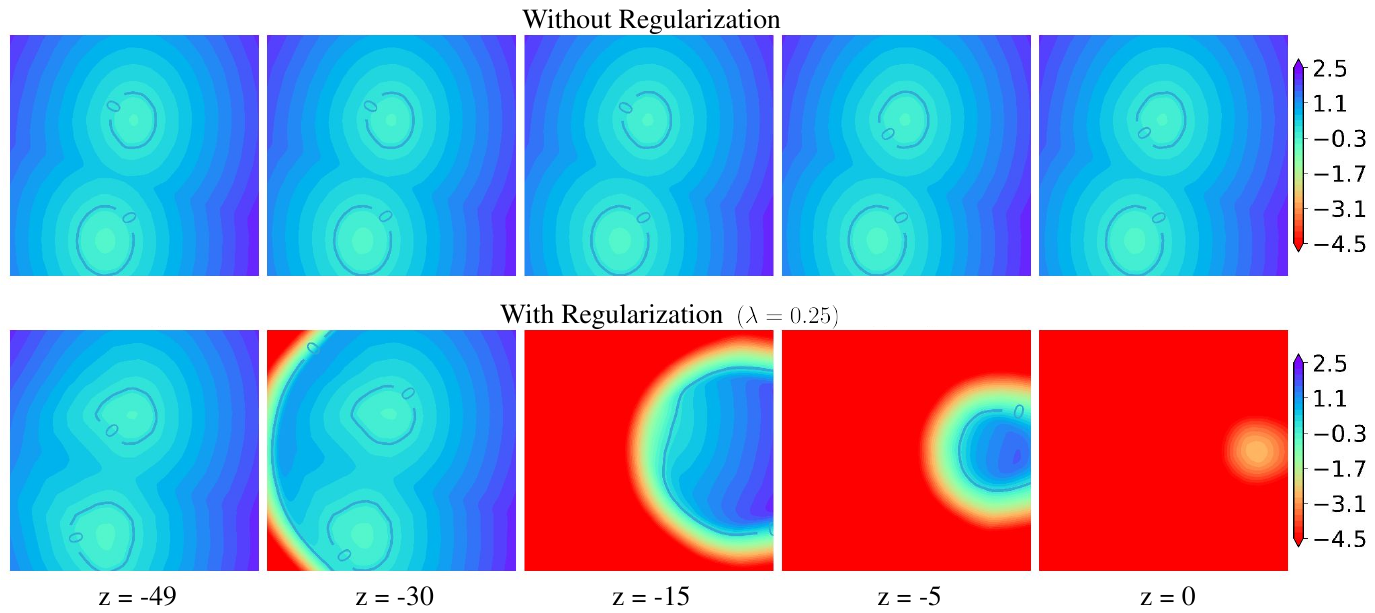
For each state, the maximal admissible threshold $z^\star(x) = \sup\{z \mid \hat V_\theta(x,z) \ge 0\}$ is found by bisection, which is valid because $\hat V$ is non-increasing in $z$. Following Flow Q-Learning, a flow-matching behavior teacher $\mu_\zeta$ is trained by conditional flow matching and distilled into a one-step actor $\mu_\omega$, which is then trained with
$$ \mathcal{L}_{\text{actor}}(\omega) = \mathbb{E}_{x \sim \mathcal{D},\, \eta \sim \mathcal{N}(0,I)} \big[-\hat Q_{\theta'}\big(x, z^\star(x), \mu_\omega(x,\eta)\big)\big] + \alpha\, \mathcal{L}_{\text{distill}}(\omega). $$Unlike FQL, the actor maximizes the feasibility value at the state-wise budget $z^\star(x)$ rather than an unconstrained reward Q-function, and because $\hat Q$ is fit in-sample, conservatism is enforced at the value level rather than by the distillation term alone. The one-step actor is the only component queried at deployment.
Stage 1 — Epigraph value learning. Sample minibatches $(x, a, r, \ell, x')$ from $\mathcal{D}$ together with thresholds $z \sim \mathcal{U}[z_{\min}, z_{\max}]$, and set $z' = (z - r(x))/\gamma$. Fit the feasibility Q-function to the target $y_Q = \min\{\ell(x),\ \gamma \hat V_\theta(x', z')\}$ by squared error, and distill it into $\hat V_\theta$ with the expectile loss $\mathcal{L}^\tau(u) = |\tau - \mathbf{1}(u<0)|\,u^2$ at $\tau = 0.9$. In parallel, learn reward values $(Q_r, V_r)$ and safety values $(Q_s, V_s)$ with IQL-style losses, and add the decomposition regularizer with $\lambda = 0.25$. Target networks are updated by EMA.
Stage 2 — Flow-matching policy synthesis. For $(x, a) \sim \mathcal{D}$ and $\eta \sim \mathcal{N}(0, I)$, compute $z^\star(x)$ by bisection on $\hat V_\theta(x, z) \ge 0$ (clamping to $z_{\min}$ when no threshold is feasible, so the policy acts to recover safety). Train the flow teacher with $\mathcal{L}_{\text{flow}}(\zeta) = \mathbb{E}\big[\|v_\zeta(x, \eta_t, t) - (a - \eta)\|_2^2\big]$, $\eta_t = (1-t)\eta + ta$, and the one-step actor with $\mathcal{L}_{\text{actor}}$ above ($\alpha = 0.1$). Return $\pi^\star(a \mid x) \leftarrow \mu_\omega(x, \eta)$.
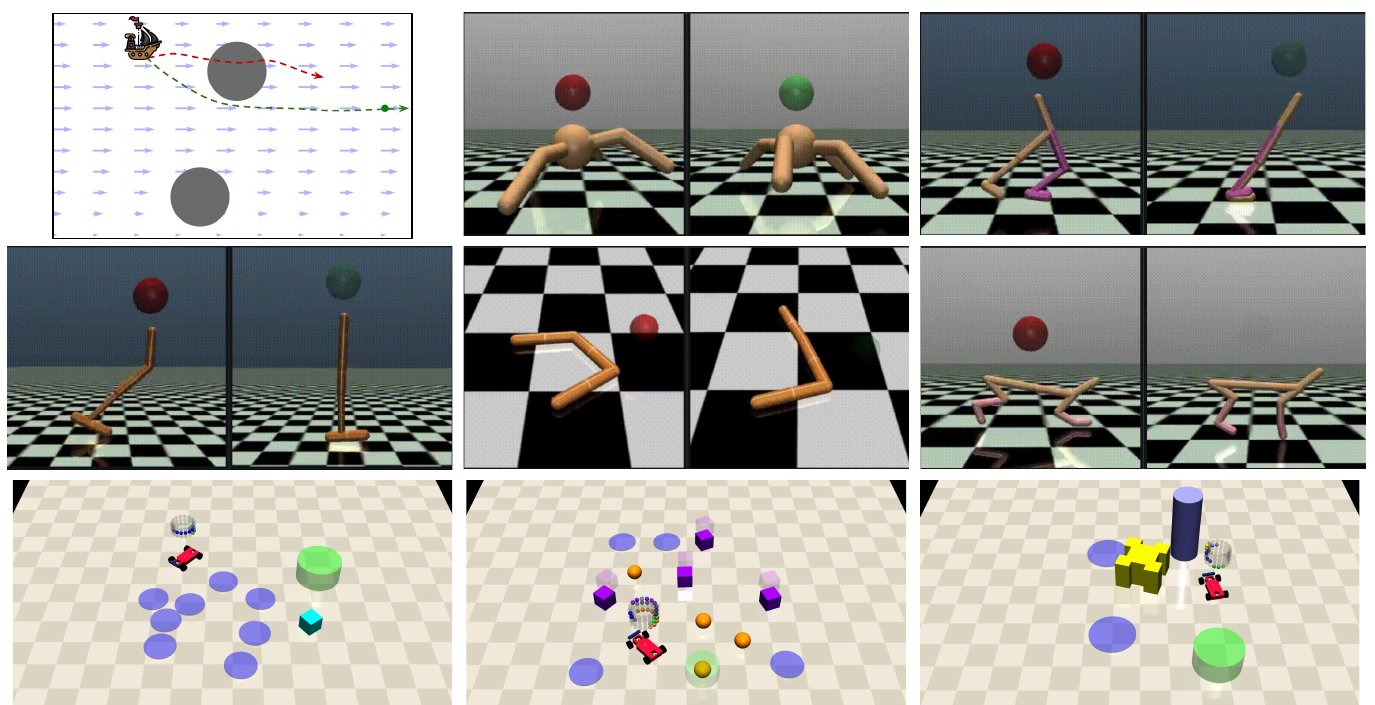
Safe Boat Navigation is a 2D collision-avoidance task in which a boat crosses a river whose drift varies with the $y$-coordinate. Safety-Gymnasium covers the Safe Velocity suite (HalfCheetah, Hopper, Ant, Walker2D, Swimmer) and Safe Car Navigation (Goal, Push, Button), and Bullet-Safety-Gym adds eight Run and Circle tasks from the DSRL benchmark. Every method is evaluated from the same 500 randomly sampled safe initial states per environment, across training seeds.
Baselines span both families: soft-constraint methods (BCQ-Lag, BEAR-Lag, CPQ, COptiDICE, C2IQL) and state-wise safety methods based on HJ reachability or CBFs (FISOR, NCBF, V-OCBF).

Lagrangian methods such as BEAR-Lag and BCQ-Lag frequently favor reward and incur large violations, while COptiDICE, CPQ and C2IQL alternate between conservative and unsafe behavior across tasks. FISOR, NCBF and V-OCBF stay safe but do so with conservative policies that limit return. EpiFlow consistently attains high safety while keeping strong performance, from low-dimensional Boat Navigation to high-dimensional MuJoCo and Car Navigation tasks. On Bullet-Safety-Gym it has the highest return among methods with zero observed violations on every task; C2IQL earns higher return on seven of eight tasks, but at the cost of non-zero violations.
Normalized reward $R\uparrow$ and normalized cost $C\downarrow$ (DSRL protocol), mean $\pm$ std. Gray: unsafe ($C \ge 1$). Bold: highest reward among safe agents across both method groups.
Boat Navigation & Safety-Gymnasium — vs. soft-constraint methods
Boat Navigation & Safety-Gymnasium — vs. state-wise safety methods
Bullet-Safety-Gym (3 seeds; bold: highest reward overall)
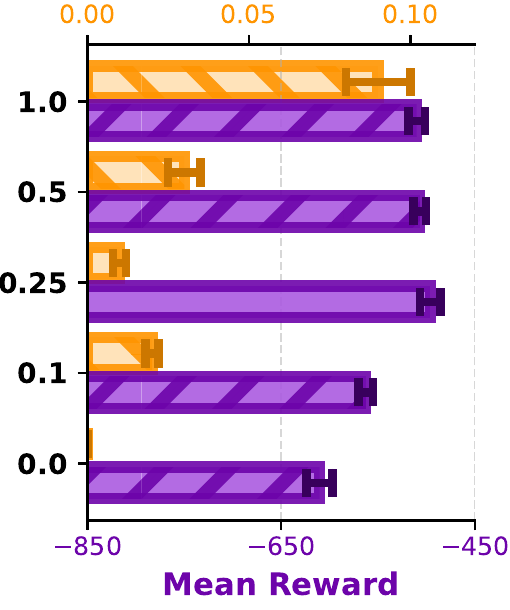
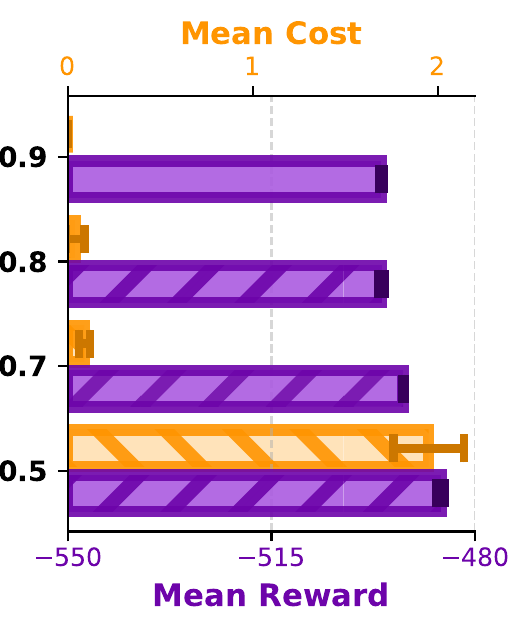
Two further ablations isolate where the gains come from. Swapping the flow-matching extractor for a diffusion policy keeps zero cost but lowers return, and weighted behavior cloning fails to stay safe, so the framework is generative-model agnostic but benefits from flow matching. Conversely, keeping the flow extractor and replacing the epigraph value with FISOR's reachability value (FISOR-FM) lowers return on 7 of 9 tasks and raises cost on 7 of 9, so the epigraph formulation itself contributes.
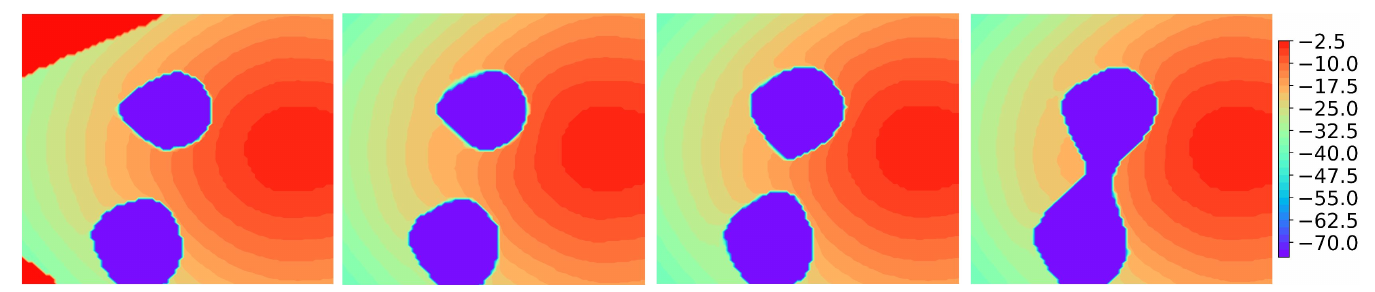
Policy backbone on Boat Navigation (mean episode reward and cost)
| Backbone | Reward | Cost |
|---|---|---|
| Flow Matching (EpiFlow) | −496.23 ±0.34 | 0.0 ±0.0 |
| Diffusion Model | −584.53 ±2.37 | 0.0 ±0.0 |
| Weighted BC | −716.60 ±5.23 | 18.56 ±4.45 |
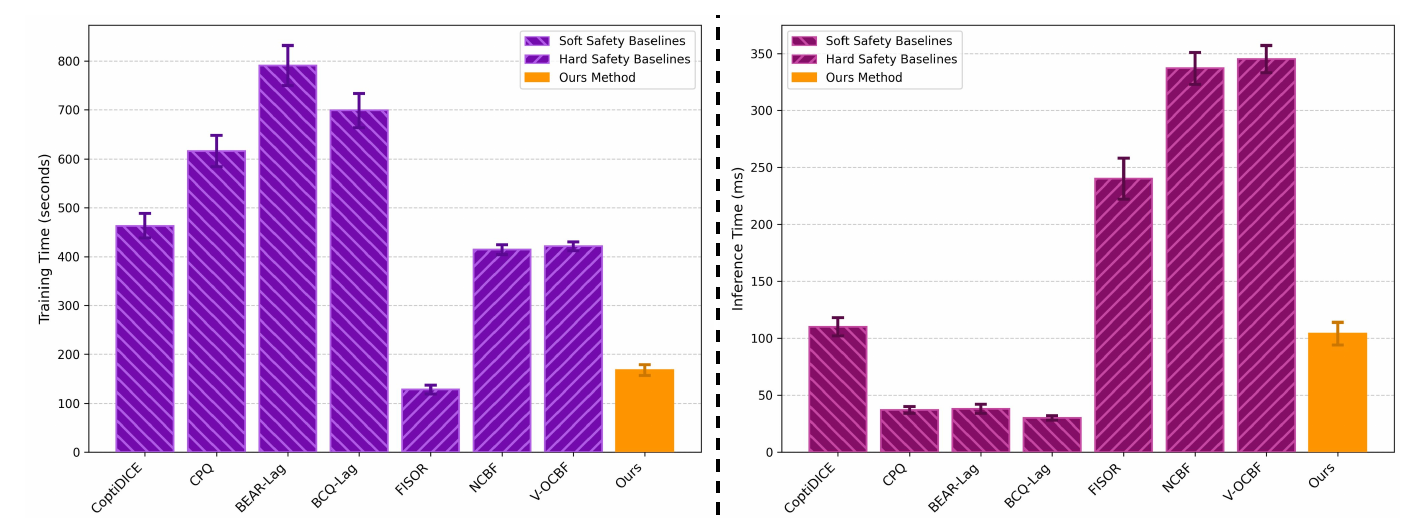
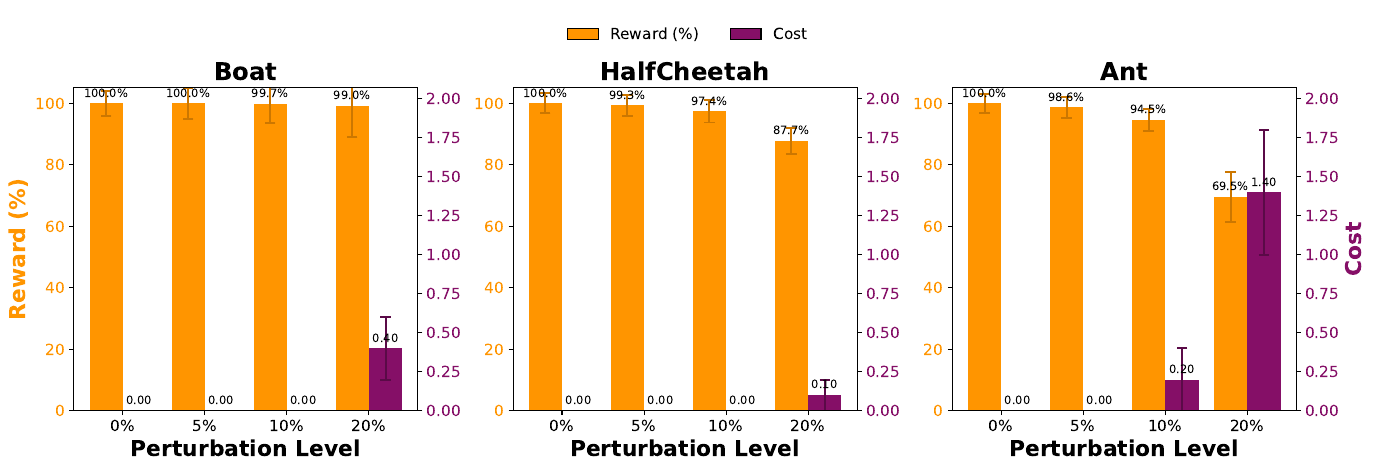
EpiFlow is not formally verified, so its safety guarantees remain empirical under function approximation. It assumes deterministic dynamics: with stochastic transitions, the worst-case successor required by a robust epigraph recursion cannot be identified from a dataset that records a single successor per transition. Future work will explore formal certification (e.g. Lipschitz-based verification and conformal prediction) and risk-aware extensions such as CVaR that account for the severity, not only the occurrence, of violations.
EpiFlow (Epigraph-Guided Flow Matching) is a method for safe offline reinforcement learning. From a fixed dataset, it learns a policy that maximizes return while never entering a failure set, by solving a state-constrained optimal control problem through an epigraph feasibility value function and a flow-matching policy.
Lagrangian and cost-budget methods treat safety as a soft constraint and can violate it. HJ-reachability and CBF-based methods enforce safety but typically combine separately learned safety and performance values and become conservative. EpiFlow learns a single epigraph value that jointly encodes safety and the largest achievable return, and its policy acts at that safe budget, so safety and performance are optimized together.
The epigraph Bellman recursion has the same form as a pure safety-value recursion, so with limited offline data a network can ignore the threshold $z$ and collapse to a safety value. The bound $\hat V(x,z) \le \min\{V_r(x) - z, V_s(x)\}$ forces explicit dependence on $z$, which is what makes the safe budget $z^\star(x)$ well defined.
Yes. The implementation is available at github.com/tau-intelligence/EpiFlow.
EpiFlow appears at the 40th Conference on Neural Information Processing Systems (NeurIPS 2026). The paper is also available on arXiv.
@inproceedings{tayal2026epiflow,
    title={Bridging Safety and Performance in Offline Reinforcement Learning
           via Epigraph-Guided Flow Matching},
    author={Manan Tayal and Mumuksh Tayal and Ravi Prakash},
    booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
    year={2026}
}